Public
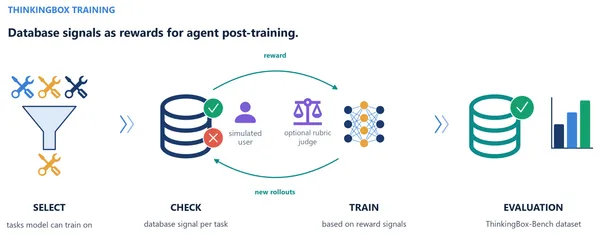
Turning Database Grading into RL Rewards: Post-Training Agents with ThinkingBox
OlmoEarth v1.3: State-of-the-art embeddings for the whole planet
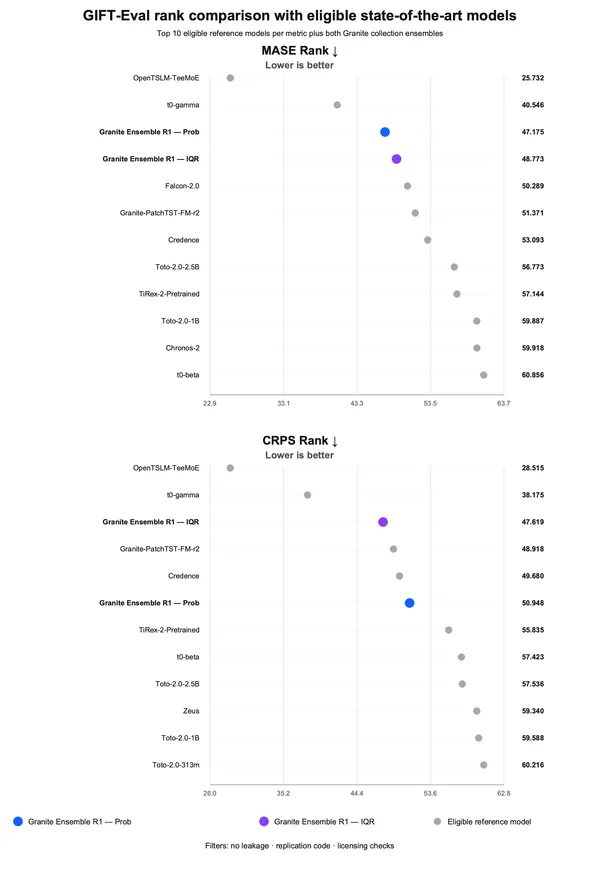
Ensemble forecasting with IBM Granite time-series models
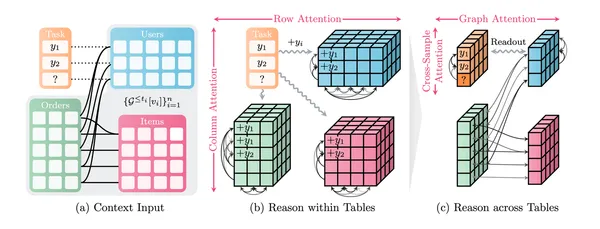
NVIDIA Kumo Relational Outperforms Supervised Machine Learning on Relational Data, No Training Required
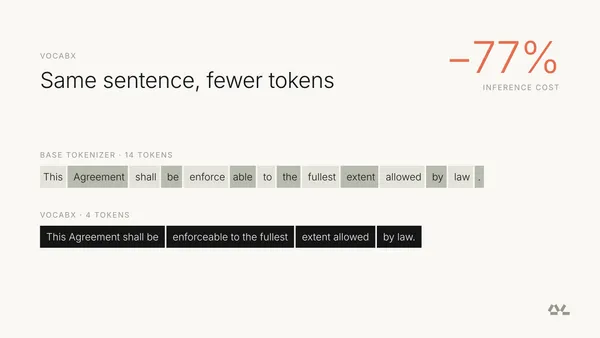
How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications
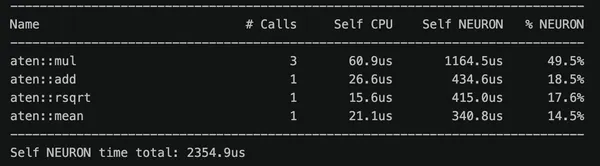
Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.
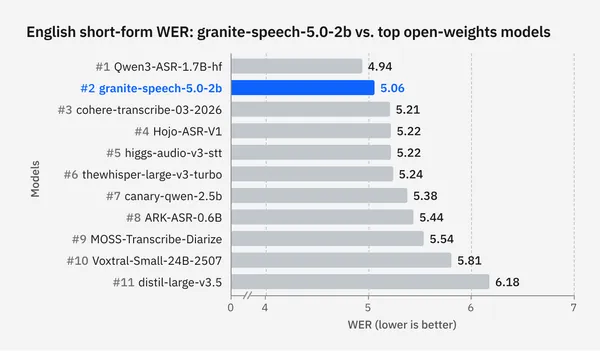
Granite Speech 5.0: Transcribe, Translate, and Attribute more Accurately and Faster
NVIDIA Kumo Forecast Combines Pretrained Time-Series Representations with Historical Pattern Retrieval and Interpretability
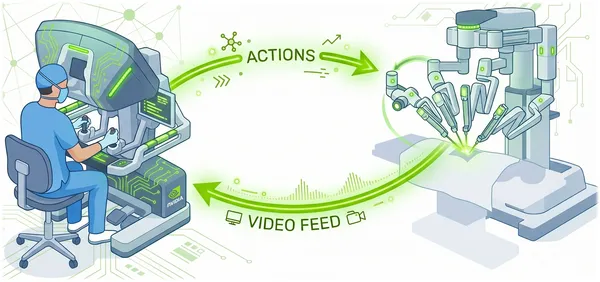
NVIDIA Cosmos3-H-Dreams: Bringing Clinical Surgery to Life Through Generative Simulation
FairStress: A deeper evaluation of fairness in LLM decision-making
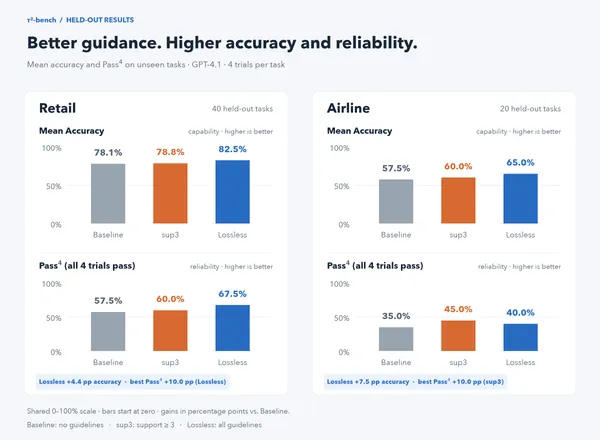
ALTK-Evolve: How learned memory tops the τ²-bench leaderboard on customer service tasks without a frontier model
Hugging Face ❤️ TorchTPU: TPUs, Natively
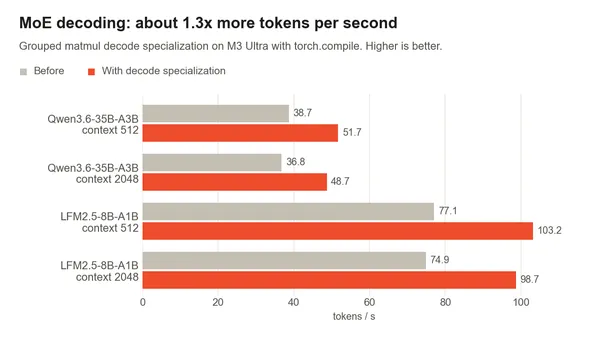
MPS in PyTorch 2.15
AnyLanguageModel 1.0: One Year of Local Models on Apple Platforms
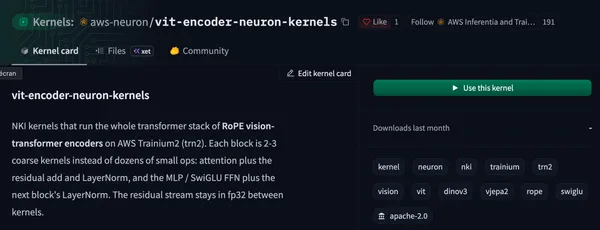
TorchNeuron: running HF models on AWS Trainium is easier than ever
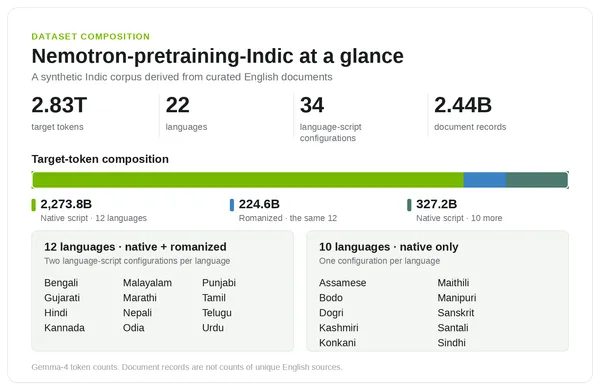
Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline
Welcome Beam: a 501B open model you can own, customize, and scale
Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint